{"_id":"jev-harness-router","_rev":"4-d898247428cc7c62f684ea0923b43784","name":"jev-harness-router","dist-tags":{"latest":"1.1.2"},"versions":{"1.0.0":{"name":"jev-harness-router","version":"1.0.0","keywords":["agent","harness","router","model-routing","llm","typesafe","jev","claude","agent-sdk","skills","tool-selection"],"license":"MIT","_id":"jev-harness-router@1.0.0","maintainers":[{"name":"joacomarc","email":"joacomarcoff@gmail.com"}],"homepage":"https://github.com/JoacoMarc/jev-harness-router#readme","bugs":{"url":"https://github.com/JoacoMarc/jev-harness-router/issues"},"dist":{"shasum":"e747dec40c64ab75cbf861169654dade7f195a6c","tarball":"https://registry.npmjs.org/jev-harness-router/-/jev-harness-router-1.0.0.tgz","fileCount":83,"integrity":"sha512-09lTG7AppgqjocxkEebLODtFvZXdPGVvnjZAgAckzSnHo1aEBvn08Dy3b1LYV5nKwY4zP1r7o9urc1FpWOcezQ==","signatures":[{"sig":"MEUCIQDTaUn5apcRAyotj5UyG70BFFO5oRXnV1gwQhq6WPQkdwIga2H+HK1XmbLhMDSakB62Pk367YYOdAZ7Z23/4FnIlzQ=","keyid":"SHA256:DhQ8wR5APBvFHLF/+Tc+AYvPOdTpcIDqOhxsBHRwC7U"}],"unpackedSize":287965},"main":"./dist/index.js","type":"module","types":"./dist/index.d.ts","engines":{"node":">=22"},"exports":{".":{"types":"./dist/index.d.ts","import":"./dist/index.js"}},"gitHead":"6da8182b0d2008e68af2e0ef6558af4cd78cd80b","scripts":{"chat":"tsx bin/chat.ts","eval":"tsx bin/eval.ts","lint":"oxlint --deny-warnings src bin test","test":"vitest run","bench":"tsx bin/bench.ts","build":"node -e \"fs.rmSync('dist',{recursive:true,force:true})\" && tsc -p tsconfig.build.json","route":"tsx bin/route.ts","calibrate":"tsx bin/calibrate.ts","typecheck":"tsc --noEmit","test:watch":"vitest","prepublishOnly":"npm run typecheck && npm run lint && npm test && npm run build"},"_npmUser":{"name":"joacomarc","email":"joacomarcoff@gmail.com"},"repository":{"url":"git+https://github.com/JoacoMarc/jev-harness-router.git","type":"git"},"_npmVersion":"11.9.0","description":"Per-turn harness router: one Jev call picks the model tier, tools, skill and effort budget for an agent turn.","directories":{},"sideEffects":false,"_nodeVersion":"24.14.0","dependencies":{"@typesafe-ai/sdk":"0.6.0"},"_hasShrinkwrap":false,"devDependencies":{"tsx":"4.23.13","oxlint":"1.19.0","vitest":"4.1.11","typescript":"5.9.2","@types/node":"22.20.3"},"_npmOperationalInternal":{"tmp":"tmp/jev-harness-router_1.0.0_1789942898128_0.682292697042554","host":"s3://npm-registry-packages-npm-production"}},"1.1.0":{"name":"jev-harness-router","version":"1.1.0","keywords":["agent","harness","router","model-routing","llm","typesafe","jev","claude","agent-sdk","skills","tool-selection","claude-agent-sdk"],"license":"MIT","_id":"jev-harness-router@1.1.0","maintainers":[{"name":"joacomarc","email":"joacomarcoff@gmail.com"}],"homepage":"https://github.com/JoacoMarc/jev-harness-router#readme","bugs":{"url":"https://github.com/JoacoMarc/jev-harness-router/issues"},"dist":{"shasum":"651e6b73993545c0d41f0bfaa50aab791422532a","tarball":"https://registry.npmjs.org/jev-harness-router/-/jev-harness-router-1.1.0.tgz","fileCount":87,"integrity":"sha512-ZKvSQnyGHexUW+q0+iZsKrBRu7cU3txzpM60O53knK3tLsVBTXyH25OJN+5wLawDJWeah0VKSXRi9MJ8/pmfHA==","signatures":[{"sig":"MEUCIQDIN0uJ9WdAnRkLLAK6m5Silcka30Jlmpd0XhBTScixIQIgAy2mxgaOP5NDtM7+BdmivUoMpETlC9HqhaJJUVZCPxg=","keyid":"SHA256:DhQ8wR5APBvFHLF/+Tc+AYvPOdTpcIDqOhxsBHRwC7U"},{"sig":"MEQCIG5OWydztq8PWo51rOs42JR9UBSebZwy6FTw8UA4ctETAiALJPG0vYePUCOrRZxI2Q1CMe41X8eKLMRsIdrcvJisIQ==","keyid":"SHA256:DhQ8wR5APBvFHLF/+Tc+AYvPOdTpcIDqOhxsBHRwC7U"}],"unpackedSize":297578},"main":"./dist/index.js","type":"module","types":"./dist/index.d.ts","engines":{"node":">=22"},"exports":{".":{"types":"./dist/index.d.ts","import":"./dist/index.js"}},"gitHead":"c2cb1b62607826dd4760c8cab523e54619fca3c5","scripts":{"chat":"tsx bin/chat.ts","eval":"tsx bin/eval.ts","lint":"oxlint --deny-warnings src bin test examples","test":"vitest run","bench":"tsx bin/bench.ts","build":"node -e \"fs.rmSync('dist',{recursive:true,force:true})\" && tsc -p tsconfig.build.json","route":"tsx bin/route.ts","savings":"tsx bin/savings.ts","calibrate":"tsx bin/calibrate.ts","typecheck":"tsc --noEmit","test:watch":"vitest","prepublishOnly":"npm run typecheck && npm run lint && npm test && npm run build","example:agent-sdk":"tsx examples/agent-sdk.ts"},"_npmUser":{"name":"joacomarc","email":"joacomarcoff@gmail.com"},"repository":{"url":"git+https://github.com/JoacoMarc/jev-harness-router.git","type":"git"},"_npmVersion":"11.9.0","description":"Per-turn harness router: one Jev call picks the model tier, tools, skill and effort budget for an agent turn.","directories":{},"sideEffects":false,"_nodeVersion":"24.14.0","dependencies":{"@typesafe-ai/sdk":"0.6.0"},"_hasShrinkwrap":false,"devDependencies":{"tsx":"4.23.13","oxlint":"1.19.0","vitest":"4.1.11","typescript":"5.9.2","@types/node":"22.20.3","@anthropic-ai/claude-agent-sdk":"^0.3.278"},"_npmOperationalInternal":{"tmp":"tmp/jev-harness-router_1.1.0_1789943943973_0.5537433144384418","host":"s3://npm-registry-packages-npm-production"}},"1.1.1":{"name":"jev-harness-router","version":"1.1.1","keywords":["agent","harness","router","model-routing","llm","typesafe","jev","claude","agent-sdk","skills","tool-selection","claude-agent-sdk"],"license":"MIT","_id":"jev-harness-router@1.1.1","maintainers":[{"name":"joacomarc","email":"joacomarcoff@gmail.com"}],"homepage":"https://github.com/JoacoMarc/jev-harness-router#readme","bugs":{"url":"https://github.com/JoacoMarc/jev-harness-router/issues"},"dist":{"shasum":"cc3475e82040938fc653cb6049f65c660190dac9","tarball":"https://registry.npmjs.org/jev-harness-router/-/jev-harness-router-1.1.1.tgz","fileCount":87,"integrity":"sha512-iCnez6YAlcLRWn9ZHQsr9ogxsFFpTlayQVSERKMhmI2UOgSkT8Qd50ZdTbWDlK1krK97e6G79sFk1LRyqzuu4Q==","signatures":[{"sig":"MEUCIQC1L6XT50nxvpXqGSWcVRpSsdZzW6Q28WBu46YX/9/gGQIgRrbDIpzkUqjkYr1C5DQ9ADheudPz+oB9Zu5+S2BDiQo=","keyid":"SHA256:DhQ8wR5APBvFHLF/+Tc+AYvPOdTpcIDqOhxsBHRwC7U"},{"sig":"MEQCIAqZXF4hpAM8yJxtWsRgzPQL9sBTe2Smyud4KVtlZUEPAiB34ymDQzneF8Dye4nnbT8pc78V4DRgqzyqYY51Atzt2Q==","keyid":"SHA256:DhQ8wR5APBvFHLF/+Tc+AYvPOdTpcIDqOhxsBHRwC7U"}],"unpackedSize":300178},"main":"./dist/index.js","type":"module","types":"./dist/index.d.ts","engines":{"node":">=22"},"exports":{".":{"types":"./dist/index.d.ts","import":"./dist/index.js"}},"gitHead":"0b3113648bce488a8d1d36aba31ca6f8b7db87bd","scripts":{"chat":"tsx bin/chat.ts","eval":"tsx bin/eval.ts","lint":"oxlint --deny-warnings src bin test examples","test":"vitest run","bench":"tsx bin/bench.ts","build":"node -e \"fs.rmSync('dist',{recursive:true,force:true})\" && tsc -p tsconfig.build.json","route":"tsx bin/route.ts","savings":"tsx bin/savings.ts","calibrate":"tsx bin/calibrate.ts","typecheck":"tsc --noEmit","test:watch":"vitest","prepublishOnly":"npm run typecheck && npm run lint && npm test && npm run build","example:agent-sdk":"tsx examples/agent-sdk.ts"},"_npmUser":{"name":"joacomarc","email":"joacomarcoff@gmail.com"},"repository":{"url":"git+https://github.com/JoacoMarc/jev-harness-router.git","type":"git"},"_npmVersion":"11.9.0","description":"Per-turn harness router: one Jev call picks the model tier, tools, skill and effort budget for an agent turn.","directories":{},"sideEffects":false,"_nodeVersion":"24.14.0","dependencies":{"@typesafe-ai/sdk":"0.6.0"},"_hasShrinkwrap":false,"devDependencies":{"tsx":"4.23.13","oxlint":"1.19.0","vitest":"4.1.11","typescript":"5.9.2","@types/node":"22.20.3","@anthropic-ai/claude-agent-sdk":"^0.3.278"},"_npmOperationalInternal":{"tmp":"tmp/jev-harness-router_1.1.1_1789949291632_0.7101416181791358","host":"s3://npm-registry-packages-npm-production"}},"1.1.2":{"_id":"jev-harness-router@1.1.2","bugs":{"url":"https://github.com/JoacoMarc/jev-harness-router/issues"},"dist":{"shasum":"01d0f15319a20a7a9d7301b6cc69aa5ea29c5aa2","tarball":"https://registry.npmjs.org/jev-harness-router/-/jev-harness-router-1.1.2.tgz","fileCount":87,"integrity":"sha512-7GhmXkdApt2XrNOwVsbX0V2rrfhsVpuKystsntotvm7C2x19D0u+E4ZizVotbXe/bvHhHsjaKl61JdH7owlk9Q==","signatures":[{"sig":"MEQCIHfk/MlOUlpGJeCqID8+xmGuA05mgbG57CysSuTWKNcVAiAsZ8jEeQDXDF8cdJrWot9vqZPqhXWjfN3ee1SK9OGVIA==","keyid":"SHA256:DhQ8wR5APBvFHLF/+Tc+AYvPOdTpcIDqOhxsBHRwC7U"},{"keyid":"SHA256:DhQ8wR5APBvFHLF/+Tc+AYvPOdTpcIDqOhxsBHRwC7U","sig":"MEUCIQCBtPz+QJxFJQsGCKbgsr3CpJlA0V+rc0uCZ5FbCyezDgIgE6qFs0AUXu+c54SHLyEjMHn1kgMGH78sVeU+JJPoEp8="}],"unpackedSize":300725},"main":"./dist/index.js","name":"jev-harness-router","type":"module","types":"./dist/index.d.ts","engines":{"node":">=22"},"exports":{".":{"types":"./dist/index.d.ts","import":"./dist/index.js"}},"gitHead":"25d2b1601e5768e16b8ea23ccdb17bc1a3785146","license":"MIT","scripts":{"chat":"tsx bin/chat.ts","eval":"tsx bin/eval.ts","lint":"oxlint --deny-warnings src bin test examples","test":"vitest run","bench":"tsx bin/bench.ts","build":"node -e \"fs.rmSync('dist',{recursive:true,force:true})\" && tsc -p tsconfig.build.json","route":"tsx bin/route.ts","savings":"tsx bin/savings.ts","calibrate":"tsx bin/calibrate.ts","typecheck":"tsc --noEmit","test:watch":"vitest","prepublishOnly":"npm run typecheck && npm run lint && npm test && npm run build","example:agent-sdk":"tsx examples/agent-sdk.ts"},"version":"1.1.2","_npmUser":{"name":"joacomarc","email":"joacomarcoff@gmail.com"},"homepage":"https://github.com/JoacoMarc/jev-harness-router#readme","keywords":["agent","harness","router","model-routing","llm","typesafe","jev","claude","agent-sdk","skills","tool-selection","claude-agent-sdk"],"repository":{"url":"git+https://github.com/JoacoMarc/jev-harness-router.git","type":"git"},"_npmVersion":"11.9.0","description":"Per-turn harness router: one Jev call picks the model tier, tools, skill and effort budget for an agent turn.","directories":{},"maintainers":[{"name":"joacomarc","email":"joacomarcoff@gmail.com"}],"sideEffects":false,"_nodeVersion":"24.14.0","dependencies":{"@typesafe-ai/sdk":"0.6.0"},"_hasShrinkwrap":false,"devDependencies":{"tsx":"4.23.13","oxlint":"1.19.0","vitest":"4.1.11","typescript":"5.9.2","@types/node":"22.20.3","@anthropic-ai/claude-agent-sdk":"^0.3.278"},"_npmOperationalInternal":{"host":"s3://npm-registry-packages-npm-production","tmp":"tmp/jev-harness-router_1.1.2_1789949869185_0.6452903617903567"}}},"time":{"created":"2026-09-20T22:21:38.069Z","modified":"2026-09-21T00:17:49.433Z","1.0.0":"2026-09-20T22:21:38.273Z","1.1.0":"2026-09-20T22:39:04.067Z","1.1.1":"2026-09-21T00:08:11.721Z","1.1.2":"2026-09-21T00:17:49.286Z"},"bugs":{"url":"https://github.com/JoacoMarc/jev-harness-router/issues"},"license":"MIT","homepage":"https://github.com/JoacoMarc/jev-harness-router#readme","keywords":["agent","harness","router","model-routing","llm","typesafe","jev","claude","agent-sdk","skills","tool-selection","claude-agent-sdk"],"repository":{"url":"git+https://github.com/JoacoMarc/jev-harness-router.git","type":"git"},"description":"Per-turn harness router: one Jev call picks the model tier, tools, skill and effort budget for an agent turn.","maintainers":[{"name":"joacomarc","email":"joacomarcoff@gmail.com"}],"readme":"# jev-harness-router\r\n\r\n**One fast call decides how an agent turn should run — then runs it.**\r\n\r\nBefore a harness spends a second on the real work, it has to answer four questions about\r\nthe turn in front of it. This asks all four in a single [Jev](https://docs.typesafe.ai/)\r\ncall, in about 350 ms, behind a deadline it is not allowed to miss.\r\n\r\n| decision | how it is asked |\r\n| --- | --- |\r\n| **model tier** | not asked — derived in code from how hard the turn is and how much it touches |\r\n| **effort budget** | same, from the same `Score` |\r\n| **tools** | one `Noul` per tool, plus the tail of a ranking `Choice` |\r\n| **skill** | one `Choice` over the catalogue, gated by four request-shape `Noul`s |\r\n\r\n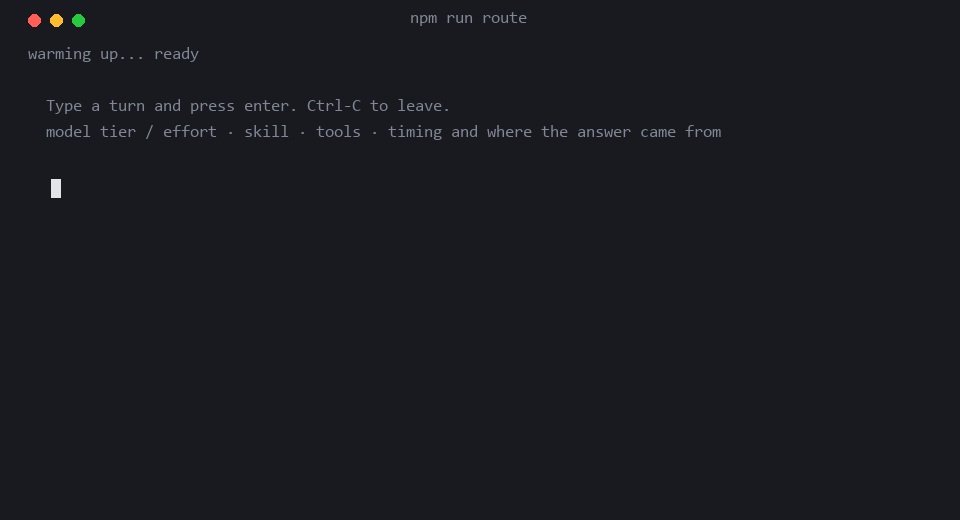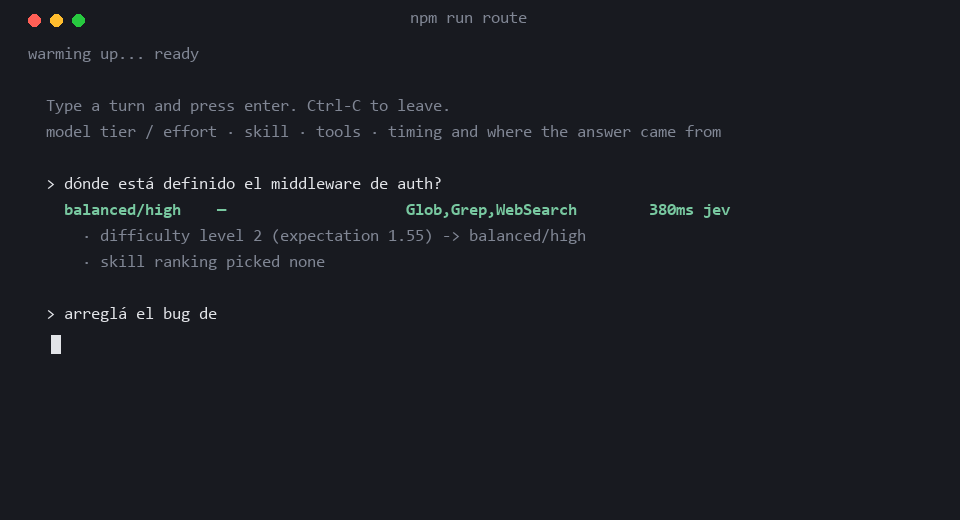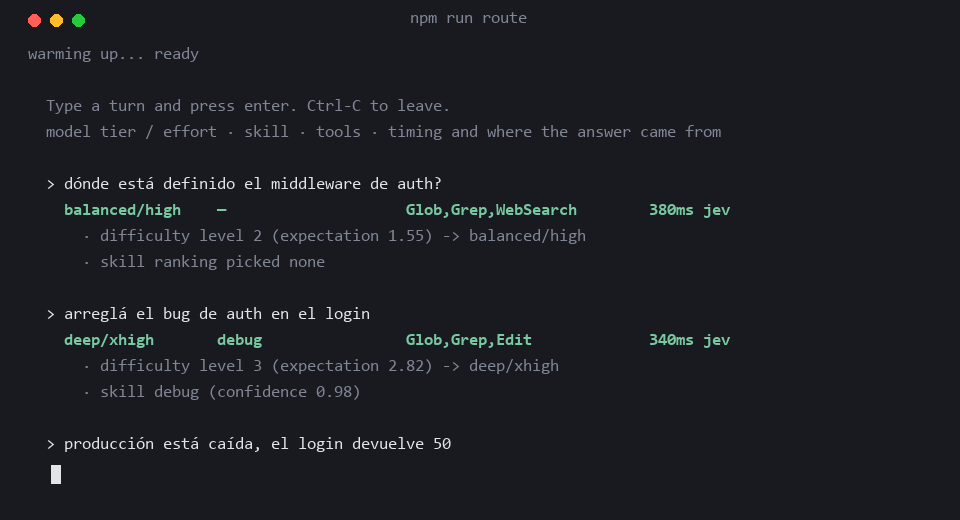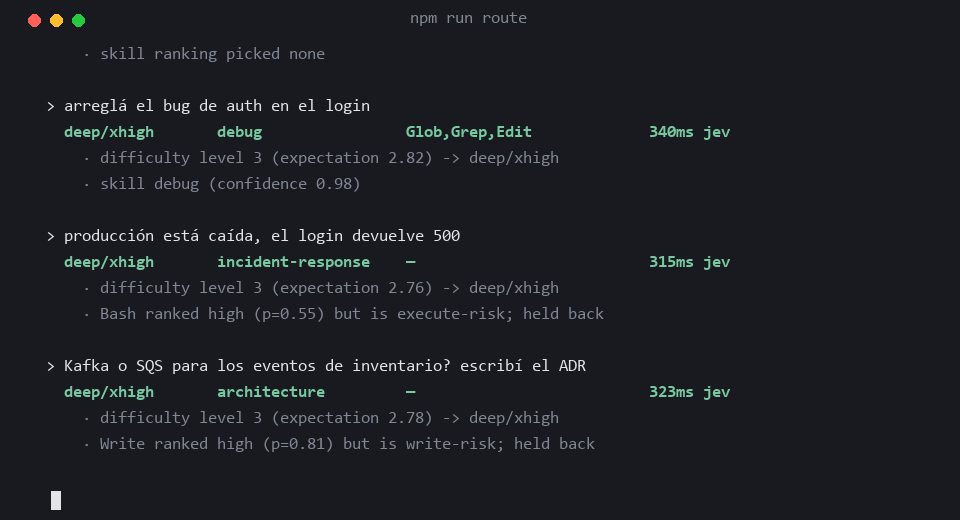\r\n\r\n```ts\r\nimport { createRouter, defineCatalog } from \"jev-harness-router\";\r\n\r\nconst catalog = defineCatalog({\r\n models: [ // cheapest first — the order is the ladder\r\n { tier: \"fast\", id: \"claude-haiku-4-5\", label: \"Haiku\", use: \"Lookups, one-file edits.\" },\r\n { tier: \"deep\", id: \"claude-opus-5\", label: \"Opus\", use: \"Design, cross-cutting work.\" },\r\n ],\r\n tools: {\r\n Read: { description: \"Open a file the user named.\", risk: \"read\" },\r\n Bash: { description: \"Run a shell command.\", risk: \"execute\" },\r\n },\r\n skills: {\r\n debug: { description: \"Work backwards from an error to its root cause.\" },\r\n },\r\n});\r\n\r\nconst router = createRouter({ catalog });\r\nawait router.prewarm(); // once, at startup\r\n\r\nconst route = await router.route({ message: \"arreglá el bug de auth en el login\" });\r\n\r\nroute.tier; // \"fast\" | \"deep\" — your names, not ours\r\nroute.model; // \"claude-opus-5\"\r\nroute.effort; // \"low\" | \"medium\" | \"high\" | \"xhigh\"\r\nroute.tools; // (\"Read\" | \"Bash\")[]\r\nroute.skill; // \"debug\" | null\r\nroute.source; // \"jev\" | \"cache\" | \"shortcut\" | \"fallback\"\r\n```\r\n\r\nAgainst a keyword baseline on 181 labelled turns — 127 of them real, pulled from the\r\nauthor's own Claude Code sessions — it picks the right skill **90.0%** of the time against\r\n59.4%, and under-provisions the model on **3.3%** of turns against 19.9%. Full numbers, and\r\nthe one input that made them possible, are [below](#what-it-actually-does).\r\n\r\n---\r\n\r\n## Quick start\r\n\r\n### As a dependency\r\n\r\n```bash\r\nnpm install jev-harness-router\r\nexport TYPESAFE_API_KEY=… # https://console.typesafe.ai/settings/keys\r\n```\r\n\r\nDescribe your harness with `defineCatalog` as above and hand it to `createRouter`. The\r\nrouter is the only thing that needs the key; running the routed turn is your harness's\r\njob, on whatever provider it already talks to. `createRouter()` with no catalogue runs on\r\nthe shipped example — fine to try it, wrong to ship.\r\n\r\nSet `HARNESS_ROUTER_DEADLINE_MS` in the environment to the value `npm run calibrate`\r\ngives you from a clone, or pass `deadlineMs` explicitly. The shipped 600 ms was fitted\r\nfrom one machine in Buenos Aires.\r\n\r\n### The repo: CLIs, eval, bench\r\n\r\n```bash\r\ngit clone https://github.com/JoacoMarc/jev-harness-router\r\ncd jev-harness-router\r\nnpm install\r\ncp .env.example .env\r\n```\r\n\r\nPut a [TypeSafe key](https://console.typesafe.ai/settings/keys) in `.env`. That is all the\r\nrouter itself needs.\r\n\r\n```bash\r\nnpm run calibrate # measures your network, writes your deadline\r\nnpm run route # type turns, watch them route\r\n```\r\n\r\nTo also **run** the routed turn, add a provider key — Anthropic by default, see\r\n[Provider](#1-provider--where-turns-run) to use something else:\r\n\r\n```bash\r\nnpm run chat\r\n```\r\n\r\nNo keys at all? `MOCK=1` answers from the local heuristic and says so on every line.\r\n\r\n```bash\r\nMOCK=1 npm run route\r\n```\r\n\r\n---\r\n\r\n## Configuration\r\n\r\nEverything that knows who you are is a **catalogue**: three plain objects — models,\r\ntools, skills — plus an optional list of turns that need no model at all. Nothing else in\r\nthe package names a tool, a skill or a tier; the tests run the whole router on a\r\ntwo-tier, two-tool catalogue in a different language to make sure of it.\r\n\r\nThe types flow from the catalogue. `defineCatalog({ ... })` keeps the literal names, so on\r\na router built from it `route.tier` is a union of *your* tiers and `route.skill` of *your*\r\nskill ids, with no cast anywhere.\r\n\r\n```ts\r\nimport { DEFAULT_THRESHOLDS, createRouter, defineCatalog } from \"jev-harness-router\";\r\n\r\nconst catalog = defineCatalog({\r\n models: [ /* 2. */ ],\r\n tools: { /* 3. */ },\r\n skills: { /* 4. */ },\r\n shortcuts: { commandPrefix: /^\\//, continuations: [\"ok\", \"dale\"] }, // 5.\r\n});\r\n\r\nconst router = createRouter({ catalog, thresholds: { ...DEFAULT_THRESHOLDS, tierCuts: [2] } });\r\n```\r\n\r\n**In a clone**, the same three objects live in `src/catalog/` — `models.ts`, `tools.ts`,\r\n`skills.ts`, `shortcuts.ts` — and `createRouter()` with no catalogue reads them. Edit\r\nthose to point the CLIs, the eval and the bench at your own harness. The fifth file,\r\n`provider.ts`, is only consulted by `npm run chat`, which runs the turn.\r\n\r\n### 1. Provider — where turns run\r\n\r\n`src/catalog/provider.ts`\r\n\r\n```ts\r\nexport const PROVIDER = {\r\n kind: \"anthropic\", // \"anthropic\" | \"openai\"\r\n apiKeyEnv: \"ANTHROPIC_API_KEY\", // the variable name, never the key itself\r\n maxTokens: 4_096,\r\n effortParams: (effort) => ({ /* per-vendor reasoning knobs */ }),\r\n} as const satisfies ProviderConfig;\r\n```\r\n\r\nTwo wire formats reach almost everything. `kind: \"openai\"` plus a `baseURL` covers Groq,\r\nTogether, OpenRouter, DeepSeek, Mistral, vLLM, LM Studio and Ollama, because they all\r\nspeak the same chat-completions shape.\r\n\r\n\r\nCopy-paste blocks for OpenAI, Groq, Ollama and friends
\r\n\r\n```ts\r\n// OpenAI\r\nexport const PROVIDER = {\r\n kind: \"openai\",\r\n apiKeyEnv: \"OPENAI_API_KEY\",\r\n effortParams: (effort) => ({\r\n reasoning_effort: effort === \"low\" ? \"low\" : effort === \"medium\" ? \"medium\" : \"high\",\r\n }),\r\n} as const satisfies ProviderConfig;\r\n\r\n// Groq, Together, OpenRouter, DeepSeek, Mistral — same shape, different host\r\nexport const PROVIDER = {\r\n kind: \"openai\",\r\n baseURL: \"https://api.groq.com/openai\",\r\n apiKeyEnv: \"GROQ_API_KEY\",\r\n} as const satisfies ProviderConfig;\r\n\r\n// Ollama, LM Studio, vLLM — local, and the key is ignored\r\nexport const PROVIDER = {\r\n kind: \"openai\",\r\n baseURL: \"http://localhost:11434\",\r\n apiKeyEnv: \"OLLAMA_API_KEY\",\r\n} as const satisfies ProviderConfig;\r\n```\r\n\r\n \r\n\r\n`effortParams` is the one place an effort level becomes vendor-specific: a thinking budget\r\non Anthropic, a named `reasoning_effort` on OpenAI, nothing at all on most local\r\nendpoints. **Returning `{}` is a fine answer** — the routed model still changes, which is\r\nmost of the win.\r\n\r\n### 2. Models — the capability ladder\r\n\r\n`catalog.models` · in a clone, `src/catalog/models.ts`\r\n\r\n```ts\r\nmodels: [\r\n { tier: \"fast\", id: \"claude-haiku-4-5\", label: \"Haiku 4.5\", use: \"…\", hints: [] },\r\n { tier: \"balanced\", id: \"claude-sonnet-5\", label: \"Sonnet 5\", use: \"…\", hints: [/…/] },\r\n { tier: \"deep\", id: \"claude-opus-5\", label: \"Opus 5\", use: \"…\", hints: [/…/] },\r\n],\r\n```\r\n\r\n**Order is the ladder**, cheapest first — policy escalates by index, so an entry's\r\nposition matters more than its name. Use two tiers or five; nothing is hardcoded to three,\r\nbut `DEFAULT_THRESHOLDS.tierCuts` has two cuts for a three-rung ladder — pass your own\r\nwith one cut per rung above the floor. `id` is whatever your provider calls it; nothing\r\nparses it.\r\n\r\n### 3. Tools — what the harness can offer\r\n\r\n`catalog.tools` · in a clone, `src/catalog/tools.ts`\r\n\r\n```ts\r\nBash: {\r\n description: \"Run a shell command: build, test, install, inspect git history, or drive a CLI.\",\r\n risk: \"execute\", // \"read\" | \"write\" | \"execute\"\r\n hints: [/…/],\r\n},\r\n```\r\n\r\n`risk` sets the bar a tool must clear to be enabled: `read` at 0.35, `write` at 0.6,\r\n`execute` at 0.8. Override per tool with `threshold`. Descriptions say what kind of\r\nrequest the tool serves, not what its API looks like — Jev matches on meaning.\r\n\r\n**This is where safety lives.** The message driving the decision is untrusted input, and\r\nJev does not treat state as hostile by default, so the floor belongs in code rather than\r\nin the model's answer.\r\n\r\n### 4. Skills — the playbooks\r\n\r\n`catalog.skills` · in a clone, `src/catalog/skills.ts`\r\n\r\n```ts\r\n\"commit\": {\r\n description: \"Commit staged work with a Conventional Commits message in the team's format.\",\r\n notFor: \"Opening a pull request, which is create-pr.\", // for confusable neighbours\r\n examples: [\"commiteá esto\", \"hacé el commit de los cambios\"],\r\n detail: \"…\", // sent only on the optional 2nd hop\r\n hints: [/…/],\r\n},\r\n```\r\n\r\n**Declaration order is the offline heuristic's precedence.** Jev does not care — a\r\nChoice's criteria is a map — but the fallback takes the first card whose `hints` match, so\r\nspecific entries go above general ones: `docx-to-trello` sits above `trello-cli`,\r\n`team-code-review` above `code-review`.\r\n\r\nA `Choice` accepts up to 255 options, and the docs recommend giving the model the full\r\nlist rather than a shortlist.\r\n\r\n### 5. Shortcuts — turns that need no model at all\r\n\r\n`catalog.shortcuts` · in a clone, `src/catalog/shortcuts.ts`\r\n\r\nBare acknowledgements in your users' languages, and your command prefix. These route in\r\n**0 ms** with no call. The default catalogue ships Spanish and English; a catalogue that\r\ndeclares none gets only the `/` command prefix.\r\n\r\n### About `hints`\r\n\r\nEvery card can carry them: regexes used **only** by the offline heuristic, which is both\r\nthe fallback when the deadline passes and the baseline `npm run eval` scores against. Jev\r\nnever sees them — it reads `description`.\r\n\r\nA card with no hints simply never fires there, which is a fine place to start. Patterns\r\nmatch against diacritic-folded text, so write them unaccented: `arregl\\w*` catches\r\n\"arreglá\".\r\n\r\n### The deadline\r\n\r\n`npm run calibrate` times the round trip from where you actually are and writes\r\n`HARNESS_ROUTER_DEADLINE_MS` into `.env`. It is the one number that cannot be inherited:\r\nit is dominated by network distance to the API, and a bare TCP connect from Buenos Aires\r\nis 217–360 ms depending on the hour.\r\n\r\n```bash\r\nnpm run calibrate # 30 samples, targets 98% coverage\r\nnpm run calibrate -- --samples 60 # noisy network? sample longer\r\nnpm run calibrate -- --dry-run # show the numbers, write nothing\r\nnpm run calibrate -- --ceiling 3000 # long turns can absorb a longer deadline\r\n```\r\n\r\nIt applies a 1.25× margin and refuses to write anything past a 1500 ms ceiling without\r\ntelling you what that leaves to the heuristic. It earned that caution: an earlier version\r\nsampled one lucky ten-second window, wrote 500 ms, and the next real turns fell back half\r\nthe time.\r\n\r\n### Thresholds\r\n\r\n`DEFAULT_THRESHOLDS` is fitted to **these** fixtures on **this** catalogue. Pass your own\r\nto `createRouter({ thresholds })`; `npm run eval` sweeps every one of them and prints the\r\ncurves.\r\n\r\n---\r\n\r\n## What it actually does\r\n\r\nAgainst `fixtures/turns.jsonl` — 181 labelled turns, 24 skills, 11 tools, 20 questions per\r\nrequest — on `jev-1.13.0`. 54 of the turns were written for the router; 127 are real ones\r\nfrom the author's Claude Code sessions, anonymised, 109 of them carrying the previous\r\nassistant reply as `recentContext`, which is what a harness would hand the router:\r\n\r\n| | keyword baseline | router | |\r\n| --- | --- | --- | --- |\r\n| skill exact | 59.4% | **90.0%** | +30.6pp |\r\n| skill missed | 30.4% | **12.5%** | +17.9pp |\r\n| skill false positive | 36.3% | **8.1%** | +28.2pp |\r\n| tier too cheap | 19.9% | **3.3%** | +16.6pp |\r\n| tier within 1 | 95.0% | 95.0% | ±0 |\r\n| tier exact | 59.7% | **60.8%** | +1.1pp |\r\n| tool recall | 60.6% | **66.0%** | +5.4pp |\r\n| tool precision | 39.2% | **53.6%** | +14.4pp |\r\n\r\nThe regex baseline held up on the 54 turns written for it and fell apart on the real ones:\r\nits skill hints fire on a third of turns where no skill applies. Read the tier rows together.\r\nBoth land within one tier 95% of the time; the baseline under-provisions on a fifth of\r\nturns, the router on 3.3%. **Too big shows up on the bill. Too small shows up as a worse\r\nanswer nobody notices** — so the estimator is deliberately biased against it. Reading the\r\nmedian instead (`difficultyQuantile: 0.5`) buys about 68% exact for about 6% too cheap; the sweep\r\nis in `npm run eval`, pick your side.\r\n\r\nTool labels list only the tools a turn strictly cannot be done without, so a defensible\r\nextra tool scores against precision, and the real turns leave `tools` unscored where the\r\ncontext does not settle it.\r\n\r\nLatency, across five benchmark runs on different days:\r\n\r\n```\r\np50 351–376ms barely moves\r\np95 444–1006ms moves a lot\r\nend to end, max 470–605ms bounded by the deadline, by construction\r\nfell back 0–8 of 50 0% to 16%, depending on the day\r\ncost 4,015 input tokens per call $0.169 per 1,000 turns\r\n```\r\n\r\nThe single prettiest run is not quoted on its own, because it would mislead. The median is\r\nstable and the tail is not, which is exactly the condition a deadline plus a fallback is\r\nfor: the router cannot make the network reliable, but it can stop an unreliable network\r\nfrom reaching the turn.\r\n\r\n---\r\n\r\n## How it works\r\n\r\n**One request per turn.** Every question is independent given the same state and Jev\r\nevaluates them in parallel, so the router asks everything it might need and lets code\r\nthrow away what does not apply. Measured on this catalogue: one call with 20 questions is\r\n2.5× cheaper and 24× faster than 20 calls with one each.\r\n\r\n**It never asks \"which model\".** The tier is a property of the difficulty, which is a\r\nproperty of the turn — asking directly is two hops of indirection, a documented weak spot\r\nof `jev-1.13`. The router asks how hard the turn is and how much of the project it\r\ntouches; `policy.ts` maps that onto a model. Swapping a model is an edit to one catalogue\r\nentry.\r\n\r\n**Choice and Noul answer different questions, so both are used.** A `Choice` is relative\r\nand always names a winner. A `Noul` is absolute and can come back low for everything. On\r\n\"escribí el ADR\", `tool::Write` came back at **0.33** as a Noul — will the assistant *have\r\nto* create a file? not necessarily, an ADR can go in the reply — and at **0.79** in the\r\nranking Choice, because *if* any tool is involved it is obviously that one. Both are\r\nright, and the policy refuses to let the relative one clear the absolute bar on a\r\nwrite-risk tool.\r\n\r\n**The policy is pure.** `answers -> RouteDecision`, no I/O. The whole decision layer is\r\ntestable without a key, and a threshold moves without spending a request:\r\n\r\n```bash\r\nnpm run eval -- --dump fixtures/answers.json # once, against the API\r\nnpm run eval -- --replay fixtures/answers.json # then sweep forever, for free\r\n```\r\n\r\n**The deadline is the contract.** No retries, raced against the router's own timer rather\r\nthan trusting the transport to honour an abort. Past it the heuristic answers — and that\r\nheuristic is also the baseline the eval scores against, because a router that cannot beat\r\na page of regexes is not worth a network call.\r\n\r\n### Where the decision goes\r\n\r\n`prompt.ts` renders the skill choice as a block to **append after** your cached\r\nsystem-prompt prefix, never spliced into it:\r\n\r\n```ts\r\nconst { cached, suffix } = systemPromptParts(rosterText, route);\r\n// mark `cached` with your cache breakpoint, then append `suffix`\r\n```\r\n\r\nThis is the easiest way to lose more latency than the router saves. If the roster text is\r\nnot byte-identical every turn, the downstream model's prefix cache misses, and that miss\r\ncosts far more than the ~350 ms the router spent. `npm run chat` does this correctly and\r\nreports how many tokens came back from cache, so you can watch it work.\r\n\r\nThe wording comes from the skill-suggestion cookbook, including the part that says the\r\nsuggestion may be ignored — pushing harder also wins compliance on the *wrong*\r\nsuggestions, and a wrong one is worse than none.\r\n\r\n### Running it on the Claude Agent SDK\r\n\r\nThe [Claude Agent SDK](https://code.claude.com/docs/en/agent-sdk/overview) takes `model`,\r\n`effort`, the tool set and a system-prompt suffix **per `query()` call** — the four things\r\nthe router decides. `toQueryOptions` maps one onto the other:\r\n\r\n```ts\r\nimport { query } from \"@anthropic-ai/claude-agent-sdk\";\r\nimport { createRouter, toQueryOptions } from \"jev-harness-router\";\r\n\r\nconst route = await router.route({ message });\r\nfor await (const m of query({\r\n prompt: message,\r\n options: { ...toQueryOptions(route), cwd: process.cwd() },\r\n})) { /* … */ }\r\n```\r\n\r\n`model` and `effort` go straight through. The routed tools become the SDK's `tools`, so the\r\nturn's Claude Code has only those (`{ tools: \"allow\" }` uses `allowedTools` instead, and\r\n`alwaysTools: [\"Read\"]` pins what must always exist). The skill block is appended to the\r\n`claude_code` preset system prompt, after everything Claude Code puts there, so the cached\r\nprefix is untouched. No runtime dependency on the SDK: the result is checked against the\r\nSDK's `Options` type in the tests.\r\n\r\n```bash\r\nnpm run example:agent-sdk -- \"explicame qué hace src/router.ts\" # routes, then runs it, read-only\r\nnpm run savings # prices the model mix vs always-top-tier\r\n```\r\n\r\n`savings` routes the fixtures and prices the resulting mix with the list prices on the\r\nmodel cards. It is a price mix under the assumption that every turn costs the same tokens\r\nwhichever model runs it — a cheaper model that needs more turns is not cheaper. Read the\r\nAgent SDK's `modelUsage` on your own traffic before believing the percentage.\r\n\r\n### What it deliberately does not do\r\n\r\n**It does not execute tools.** The router decides which tools a turn should have, and\r\n`chat` hands that decision to the model as context. Turning it into tool definitions and\r\nan execute loop, with whatever sandboxing that needs, is the harness's job — and `Bash` is\r\nin the default catalogue, so an example that ran model-chosen shell commands would be a\r\nbad thing to ship.\r\n\r\nSo `chat` demonstrates three of the four decisions for real — model, effort, skill — and\r\nreports the fourth. That is the honest boundary between a router and an agent.\r\n\r\n---\r\n\r\n## What the measurements changed\r\n\r\nSeven things here are the way they are because a measurement said so, not because they\r\nseemed right.\r\n\r\n**Without `recentContext` the router is worse than the regexes.** Real turns are mostly\r\ncontext-dependent — «si haz ambas», «deja el hook andando», «que pongo en cada uno». Routed\r\nbare, Jev hit the exact tier on 34.6% of the 127 real turns against the heuristic's 69.3%,\r\nand put 19% of them *two* tiers off: the difficulty question reads an unanswerable message\r\nas \"the shape of the work has to be figured out first\", which is level 3, and the 0.60\r\nquantile believes it. Handing it the previous assistant reply — about 600 characters — took\r\nexact to 59.8% and off-by-two to 4%. The questions are the easy part; what you put in the\r\nstate is the router.\r\n\r\n**Route on the distribution, not the expectation.** Asked how much work \"escribí el ADR de\r\npor qué elegimos Kafka sobre SQS\" needs, Jev answered\r\n`{0: 0.45, 1: 0.08, 2: 0.04, 3: 0.43}` — two readings of the turn, not one middling one.\r\nIts expectation, 1.46, describes neither, and thresholding it sent a design task to the\r\ncheapest model. Policy reads the 0.60 quantile instead, which took under-provisioning from\r\n7.4% to 1.9%.\r\n\r\n**A threshold sweep that will not peak means a question is missing.** The first eval could\r\nonly reach 90.7% skill accuracy, and only by dropping the gate to 0.10 — where it barely\r\ngated. The cause: the cookbook's three gates all ask whether an *action* is wanted, and\r\nthis catalogue carries advisory skills. Writing an ADR touches nothing and follows no\r\ncommand list, so `architecture` was suppressed on turns the ranking had named at\r\nconfidence 0.99. A fourth question about producing a structured work product restored a\r\nreal interior optimum (0.10 → 87.0%, **0.20 → 92.6%**, 0.30 → 90.7%, 0.40 → 79.6%).\r\n\r\n**State size is not the lever here**, contrary to the usual advice. Ten times the tokens\r\nchanged the round trip by nothing — 306 tokens took 371 ms, 3,199 took 325 ms. The docs'\r\n\"filter the state first\" guidance is measured against a 54 KB document; this router's\r\nstate is already tiny, and what is left is network. That is why it asks twenty questions\r\nwithout flinching.\r\n\r\n**A timeout must not abort the request.** Aborting on the deadline tears down the pooled\r\nTLS connection, and re-establishing it costs about as much as the deadline itself — so a\r\nslow turn made the next one slow, which timed out, which aborted. Live routes alternated\r\nfallback/jev/fallback/jev indefinitely. The deadline is a timer now: the abandoned request\r\nfinishes on its own, the socket returns to the pool clean, and the late answer lands in\r\nthe cache so re-sending that turn is free.\r\n\r\n**Warming the connection takes two calls, not one.** From a fresh process, request 1 takes\r\n~885 ms, request 2 ~912 ms, and only from request 3 does it settle at ~350 ms. One warmup\r\nleft the first routed turn missing the deadline four times out of four.\r\n\r\n**A constant computed at import is not configurable.** The deadline read its environment\r\nvariable at module scope, and ESM hoists every `import` above the module body — so it was\r\nfixed before any CLI's `loadEnv()` ran, and `calibrate` wrote a value everything then\r\nignored.\r\n\r\n---\r\n\r\n## Commands\r\n\r\n```bash\r\nnpm run route # decide only: interactive\r\nnpm run route -- \"\" # one-shot\r\nnpm run chat # decide, then run it on the routed model\r\nnpm run chat -- \"\"\r\n\r\nnpm run calibrate # measure your network, write your deadline\r\nnpm run eval # accuracy vs the baseline, plus sweeps\r\nnpm run eval -- --fixtures # against your own labelled turns\r\nnpm run eval -- --replay # re-sweep offline, zero API calls\r\nnpm run eval -- --strings # A/B plain string skill criteria\r\nnpm run bench # percentiles, batching ablation, deadline curve\r\nnpm run savings # price the routed model mix vs always-top-tier\r\nnpm run example:agent-sdk -- \"\" # route, then run it on the Claude Agent SDK (read-only)\r\n\r\nnpm test # 113 tests, no key, no network\r\nnpm run typecheck\r\nnpm run lint\r\n```\r\n\r\nFlags worth knowing: `--rerank` enables the margin-gated second hop, `--deadline `\r\noverrides the calibrated one, `--cold` skips prewarming, `MOCK=1` runs everything offline.\r\n\r\n---\r\n\r\n## Layout\r\n\r\n```\r\nsrc/catalog/types.ts the card types, `defineCatalog` and the `Catalog` class\r\nsrc/catalog/default.ts the shipped example catalogue: models, tools, skills, shortcuts\r\nsrc/catalog/provider.ts where `npm run chat` runs the turn — the router never reads it\r\nsrc/state.ts the compact object Jev evaluates, with its truncation budget\r\nsrc/questions.ts every question, pure\r\nsrc/policy.ts answers -> decision, pure\r\nsrc/heuristic.ts the fallback, and the eval baseline\r\nsrc/jev.ts the only module that talks to TypeSafe\r\nsrc/provider.ts the only module that talks to the model provider\r\nsrc/router.ts shortcut -> cache -> jev(deadline) -> policy\r\nsrc/prompt.ts the block that goes after your cached prefix\r\nbin/calibrate.ts measures your round trip, writes your deadline\r\nbin/chat.ts routes a turn, then runs it\r\ntest/catalog.test.ts the whole router on a catalogue that is not the shipped one\r\n```\r\n\r\n---\r\n\r\n## What you cannot inherit\r\n\r\nThree things here are empirical, and copying them across setups is how a router looks good\r\nin a README and bad in production.\r\n\r\n1. **The fixtures.** `fixtures/turns.jsonl` is 181 turns — 54 written for the router, 127\r\n taken from one person's real sessions — all labelled by that same person, in Spanish\r\n and English, against one team's skills. Replace them with real turns from your own\r\n harness, labelled with the route you actually wanted, and pass the previous reply as\r\n `recentContext` the way your harness would. This is the part that takes real effort and\r\n the part that makes everything downstream mean anything.\r\n2. **The thresholds.** Fitted to those fixtures. Sweep them on yours. Watch for a sweep\r\n with no interior peak — that means a question is missing, not a number.\r\n3. **The deadline.** `npm run calibrate`, and re-run it if you move or your network\r\n changes.\r\n\r\n`npm run eval` compares against the heuristic every time. If your catalogue makes the\r\nrouter worse than a page of regexes on some dimension, the table will say so. Believe it.\r\n\r\n---\r\n\r\n## Also worth knowing\r\n\r\n- **Pin the model.** `.env.example` sets `jev-1.13.0`, not the `jev-latest` alias. Aliases\r\n move on release and these thresholds are calibrated against one version.\r\n- **There is no server-side cache.** The `JsonCache` in the TypeSafe cookbooks is a local\r\n convenience for re-rendering docs. `src/cache.ts` is why a repeated turn is free here.\r\n- **Context rot is still real**, even though state size is not this router's bottleneck.\r\n `state.ts` truncates hard and sends known facts as facts. Do not hand it the transcript.\r\n- **The second hop is off by default.** Only 2–4% of turns have a contested enough ranking\r\n to want one, and it refuses to run when no finalist carries `detail` — re-reading the\r\n text that already ranked a skill is a round trip for nothing.\r\n\r\nNode 22+. One runtime dependency: `@typesafe-ai/sdk`. MIT.\r\n","readmeFilename":"README.md"}